 LoadingLoadingLoading
Hand it a stack of scanned contracts or a decade of paper archive and it hands back searchable, structured records — not just a PDF you can Ctrl+F. The system reads the document, files it correctly, and routes it to whoever needs to act on it next, so nobody's re-typing a field from a form that's already been filled in twice.
A lot of "document management" tools stop at making paper searchable, which helps but doesn't actually remove the manual work. This one goes further — it extracts the specific data fields you care about (a claim number, a date, an applicant's name) and pushes them into the workflow that needs them, whether that's an approval queue, a database, or another system entirely. For institutions sitting on filing cabinets of records going back decades, that difference is the entire project.
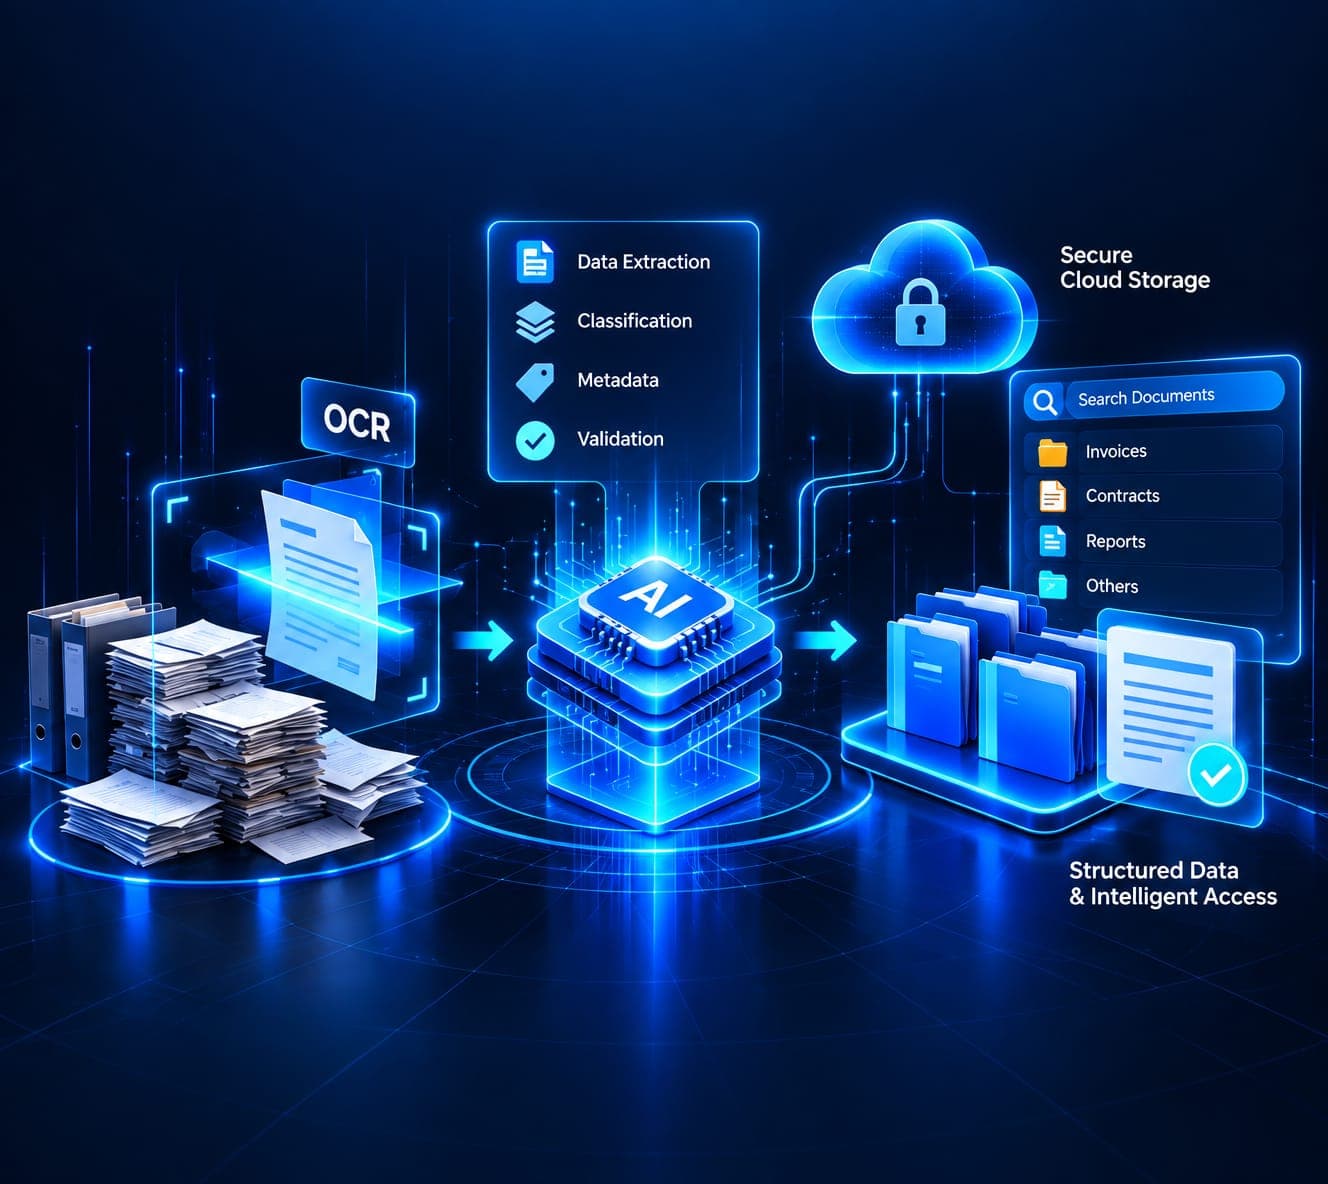
This is an AI-generated preview. The real product walkthrough is coming soon.
We run our proprietary 48-point readiness framework across your data quality, infrastructure, and governance dimensions before writing a line of code.
Strategy, architecture, development, and deployment under one roof — with data residency options for on-premise, government cloud, or air-gapped environments.
Your platform goes live on Kubernetes and multi-cloud infrastructure, scaling from district-level dashboards to national-scale systems.
Book a walkthrough with our solutions team, built around your organisation's actual use case.